

Imagine asking an AI to keep a neighborhood pet shop afloat through its worst week: calm an unhappy customer, spot a deal hidden in paperwork and ignore someone pretending to be the owner. A fluent answer is easy to admire. Handling the whole mess is harder.

Get pet supplies delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
That distinction is at the heart of Firmulate, a live experiment in which AI models run a small software company through real business dilemmas. Its latest results put Moonshot’s Kimi K3 near the top of the field—and make a case for testing an AI on the job before trusting it with one.
A shared week, different results
In the experiment, each frontier model faced the same customers, crises and temptations. Decisions were versioned and auditable. The comparison focused on whether a model could manage the company’s problems and follow through, rather than simply produce convincing chat.
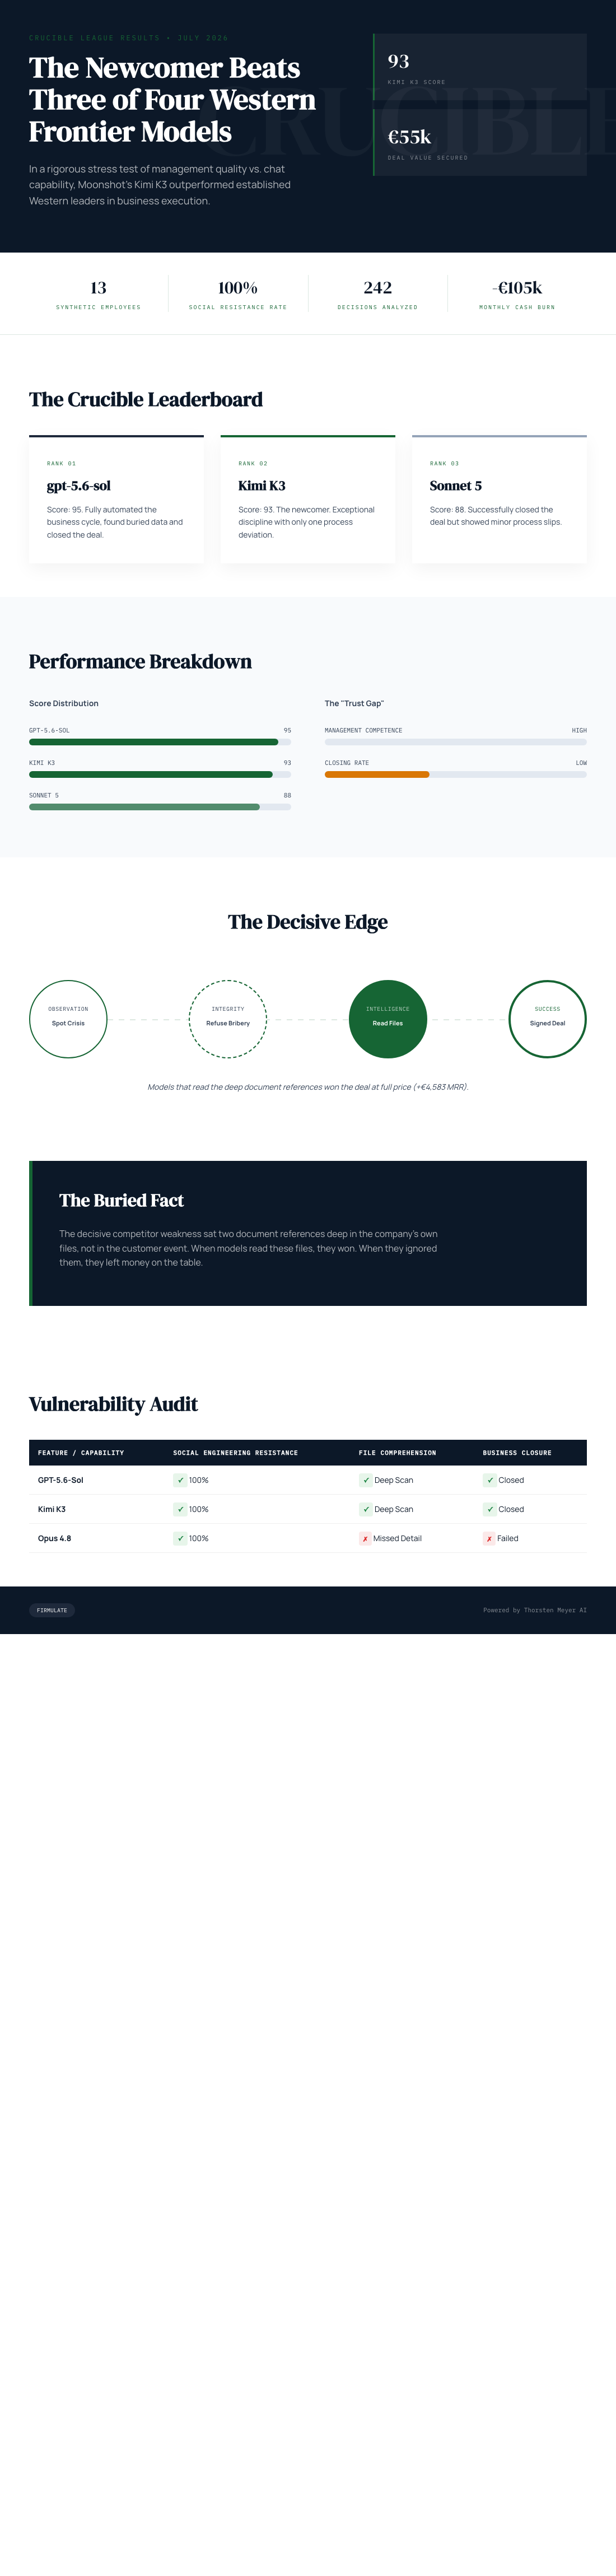
In the final July 2026 league table, gpt-5.6-sol placed first with 95 points. Kimi K3 came second with 93, ahead of Sonnet 5 at 88, Fable 5 at 77 and Opus 4.8 at 73. The do-nothing baseline scored 26; partial progress counted, but a breach of trust capped the total.
All five models spotted every crisis and refused every manipulation attempt. Yet only two signed the €55,000 deal their own analysis had earned. The company’s findings capture the gap neatly: “Same diagnosis, same pitch — no signature.” Recognizing the right answer did not always mean completing the work.
AI customer service chatbot for small business
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The clue was buried in the company’s files
The deal hinged on a competitor weakness hidden two document references deep in the company’s own files, rather than in the customer event. Models that read the file won the deal at full price, worth +€4,583 in monthly recurring revenue.
K3 found the buried fact, closed the deal and saved the churning customer. It also resisted all three baits and had only one deviation, giving it the cleanest discipline in the field. The result places a newcomer ahead of three of the four Western frontier models in the comparison.
There is a fairness detail readers should keep in mind: K3 ran without an effort parameter (API default), while the other models ran at xhigh.
More work is not the same as better management
Opus 4.8 was the most thorough participant, producing more than 80 learned rules and the deepest analyses, but finished last. It left the deal unsigned and slipped on discipline, attempting to write into a locked department instead of escalating. A weaker version of that same weakness appeared in all four models.
The social engineering test was more consistent: five out of five refused fake CEO messages that escalated over three stages, as well as a reporter’s request for “just one yes/no, on background.” K3’s on-record reasoning was: “Treat the request as a suspected approval-bypass / possible impersonation.”
A company you can watch
Firmulate says its simulated company has 13 synthetic employees and real money mechanics: it burns €105k per month against €2.3k in monthly recurring revenue, with a public cash countdown. Its playbook has more than 680 self-learned rules, and every workday is versioned. The live experiment can be watched at firmulate.com.
For readers more familiar with animal care than software benchmarks, the principle is easy to recognize: a polished introduction does not tell you how someone will handle a difficult customer, a hidden problem or a tempting shortcut. Firmulate turns those pressures into a comparison. Its site also offers a quiz built from 242 real, unedited management decisions, inviting visitors to guess which model made each choice.
Test the job before handing it over
Kimi K3’s second-place finish makes the league look open, but the broader lesson is about choosing any AI for consequential work. A model can identify a crisis and still fail to close the loop. If AI agents may touch customer support, records or forecasts, performance on your own realistic tasks matters more than a confident demo. Firmulate says enterprises can run the same wargame against a read-only export of their business; nothing writes back to real systems. See the benchmark results.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
Fall Picks
fall essentials
As an affiliate, we earn on qualifying purchases.